Practical writing on full stack software engineering — real-world patterns, not textbook theory.
Get new blog posts by email.
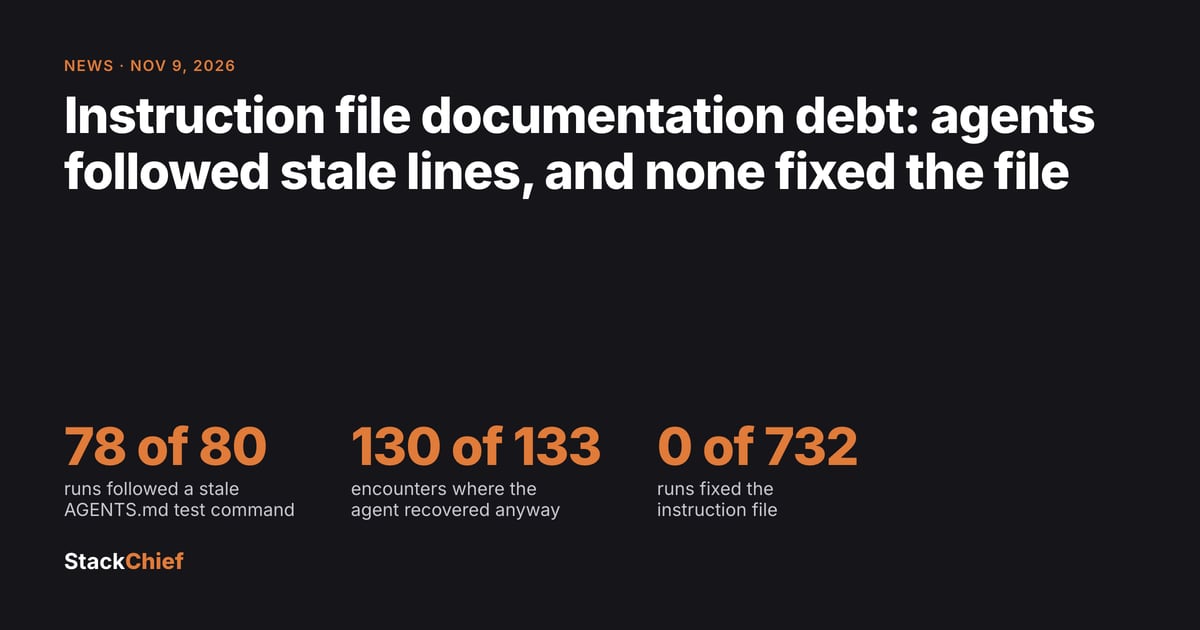
A November 6 study of 732 Claude Code runs measures what stale lines in AGENTS.md and CLAUDE.md cost: detours, test runs that check nothing, and a file no agent repairs. How it compares with October's stale-file study, and what to check in your own repositories.
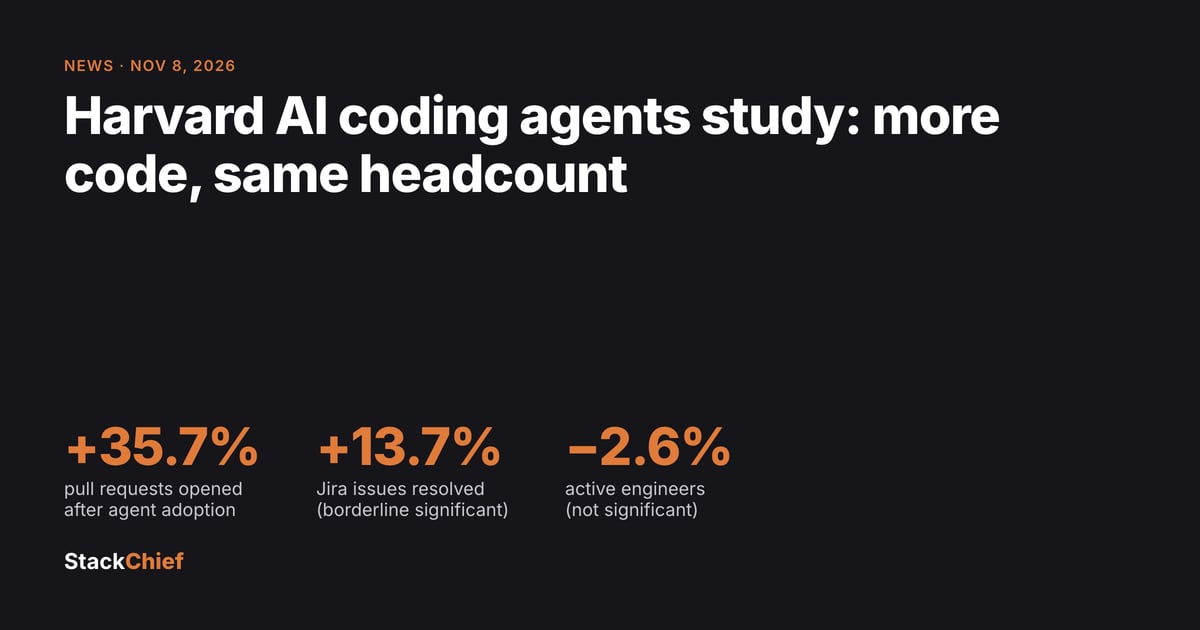
A November 7 revision of the Harvard working paper on 655 firms finds AI coding agents raise code output far more than finished work, with no detectable change in headcount. What changed from the October draft, why code review is the bottleneck, and what it means for your job.
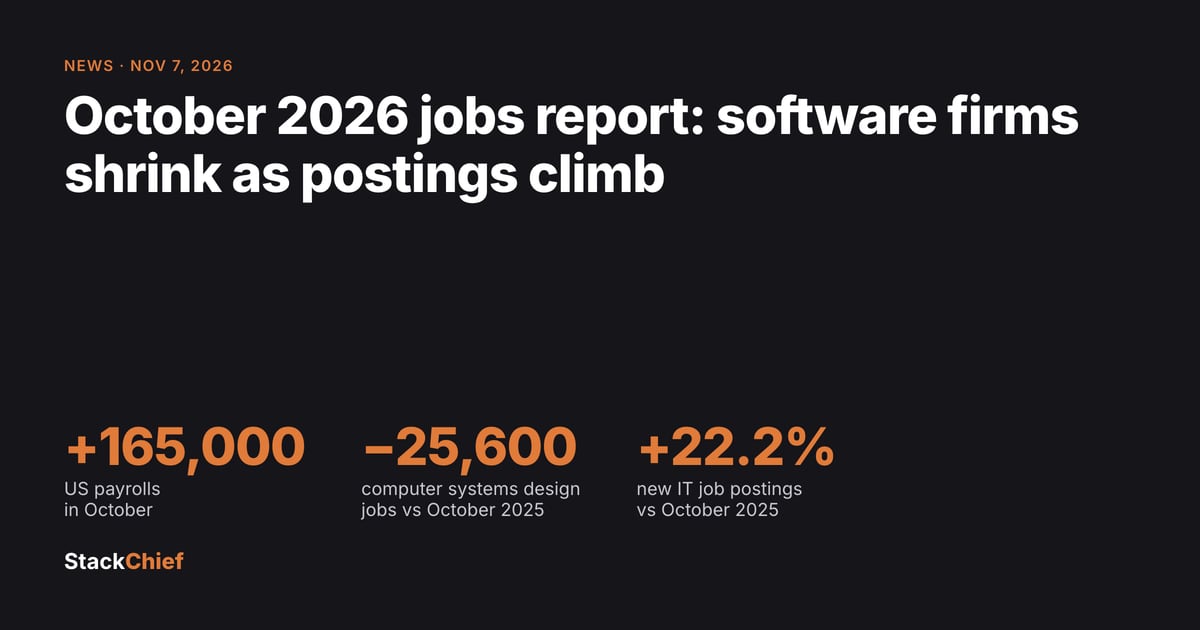
US payrolls rose 165,000 in October and tech job postings kept climbing, but employment at software services firms is still below where it was a year ago. The software-relevant BLS industry lines, set against the postings data, and what the gap means for job seekers.
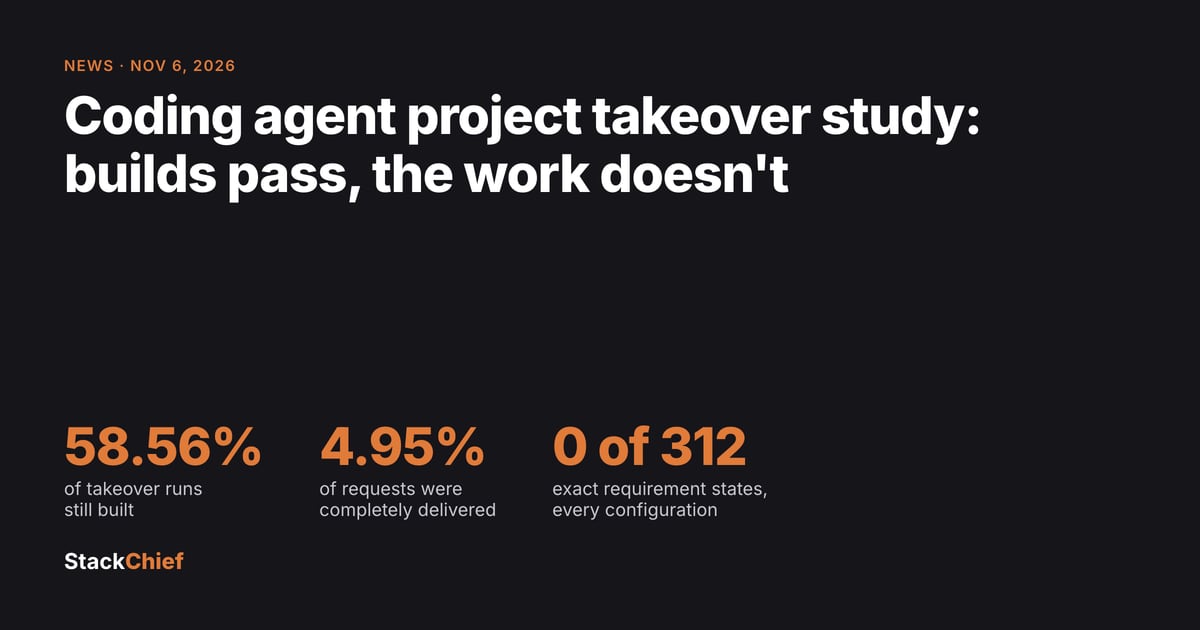
Researchers handed six Codex CLI and Claude Code setups ongoing projects, their message history and the next request. The agents kept the code building and rarely did the requested work, because they lost track of what the project currently required. What that means for handovers, and for your job.
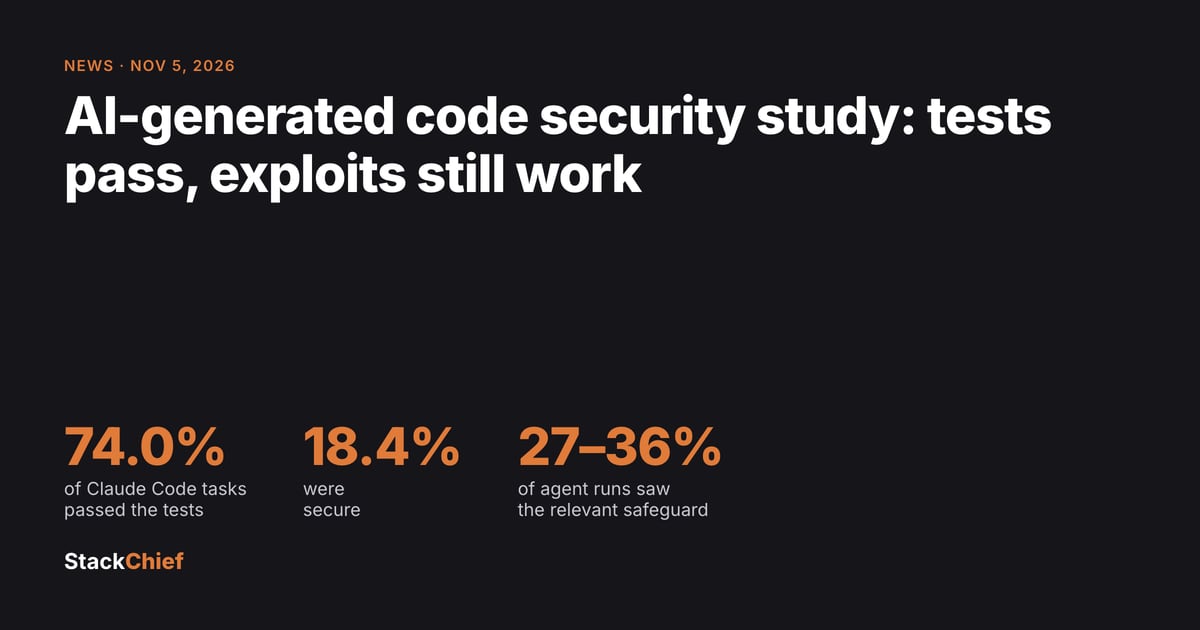
A new benchmark built from real CVEs ran Claude Code and SWE-agent on security-sensitive tasks. Most code that passed the tests could still be exploited: agents rarely found the validators and policies that kept it safe. What to change in prompts, instruction files and review.
 StackChief