
Key Takeaways
- An algorithm is a step-by-step method for solving a problem; a program implements that method in code.
- Choose algorithms around your inputs, required output, and constraints—not just a familiar name.
- Big O describes an upper bound on resource growth as input size increases, not execution time in seconds.
- Linear search works on unsorted data. Binary search needs sorted data, and preparing that data has a cost.
- Use bubble sort to understand sorting mechanics; prefer built-in sorting for ordinary application code, with an explicit numeric comparator when needed.
What is an algorithm? It's a defined sequence of steps for solving a problem, such as finding a number or putting a list in order. Understanding algorithms helps you choose solutions that remain practical as the amount of data grows.
What Are Algorithms?
Think of an algorithm as a recipe: it describes what to do, in what order, and when you're finished. The ingredients are the inputs, the instructions are the steps, and the finished dish is the output. This matches the basic idea in NIST's definition of an algorithm.
The method is separate from its implementation. You can describe a search algorithm in plain English, then implement it in JavaScript, Java, or another language. The examples below use deterministic algorithms: given the same input, they produce the same result.
Why Do Algorithms Matter?
Consider finding a customer ID in an array containing a million sorted IDs. A linear search might examine all million entries; binary search needs at most 20 midpoint checks. The difference comes from how the algorithms organize their work, not from shorter variable names or a faster loop syntax.
Memory matters too. Changing an existing array and creating a sorted copy have different memory requirements. Faster processing can also reduce the work a system needs to perform, but Big O alone doesn't establish its energy consumption or operating cost.
The practical lesson is to avoid unnecessary work first, then measure the implementation. The Princeton algorithms reference summarizes the growth rates and tradeoffs behind these choices.
Fundamental Concepts
Algorithmic Thinking: Define the Steps
Algorithmic thinking means turning a problem into explicit inputs, outputs, and steps. It isn't about “thinking like a computer”; it's about removing ambiguity.
Suppose you need the largest number in an unsorted array. You don't need to sort the entire array:
- If the array is empty, return an explicitly chosen empty result.
- Remember the first number as the largest seen so far.
- Compare each remaining number with that remembered value, updating it when necessary.
- Return the remembered value.
All JavaScript examples here assume ordinary arrays containing only finite numbers, with no empty slots. They assume valid inputs rather than validating every element. Run each block independently in a browser console or a current Node.js environment; no packages are required.
function findLargestNumber(numbers) {
  if (numbers.length === 0) return undefined;

  let largest = numbers[0];
  for (let i = 1; i < numbers.length; i++) {
    if (numbers[i] > largest) {
      largest = numbers[i];
    }
  }
  return largest;
}

console.log(findLargestNumber([1, 3, 2])); // 3
console.log(findLargestNumber([-8, -3, -3])); // -3
console.log(findLargestNumber([])); // undefined
This function returns a value, not an index. It handles negative numbers and duplicates, leaves the input unchanged, and returns undefined for an empty array. For a nonempty array of n elements, it makes n − 1 comparisons: O(n) time and O(1) extra space under the usual constant-cost model for numeric comparisons and indexed array access.
If the loop syntax is unfamiliar, review JavaScript loops before moving on.
Algorithmic Design: Turn Requirements into a Solution
Use the maximum-finding problem to work through a repeatable design process:
- Understand the problem: You need one maximum value, not a fully sorted list. Decide what empty input means.
- Design a solution: Scan once and remember the largest value seen.
- Evaluate its cost: The scan is O(n), with O(1) extra space. Comparison sorting with merge sort would take O(n log n) time to obtain more ordering information than you need.
- Test it: Try empty input, one element, duplicates, negative numbers, and a maximum at either end.
- Document the contract: State the accepted inputs, return value, empty-input policy, and whether the function changes its input.
A useful correctness argument is that after each iteration, largest holds the maximum of everything examined so far. That statement remains true as the scan advances, so it is true for the whole array when the loop finishes.
Algorithmic Complexity: Count Growing Work
Input size, usually written as n, is the quantity that grows—for these examples, the number of array elements. Time complexity describes how the work grows with n. Space complexity describes memory growth; auxiliary space means extra memory beyond the input.
For the analyses below, assume each numeric comparison and indexed array access takes constant time. These assumptions make the algorithmic model explicit; they aren't predictions of elapsed time on a particular machine.
Understanding Efficiency
Big O Notation for Beginners
Big O notation expresses an asymptotic upper bound: a limit on growth, up to a constant multiplier, once the input is sufficiently large. It can describe time or memory, and the bound isn't necessarily tight.
For example, work growing as 3n + 10 is O(n): the multiplier and fixed overhead don't change its linear growth. Big O also doesn't automatically mean worst case; say whether you're discussing best-, average-, or worst-case behavior.
These common growth rates describe very different amounts of work:
- O(1), constant: A fixed amount of work, such as reading one array position in our model.
- O(log n), logarithmic: Repeatedly reduce the remaining problem by a constant factor, as binary search does.
- O(n), linear: Examine every element once.
- O(n log n), linearithmic: The growth rate of merge sort.
- O(n²), quadratic: Work grows roughly with the square of the input size, as in the fixed-pass bubble sort below.
The following chart evaluates representative growth functions using base-2 logarithms. These are illustrative mathematical values, not benchmarks, exact operation counts, or seconds.
Growth function       n = 16     n = 256     n = 4,096
1                          1           1             1
log2(n)                    4           8            12
n                         16         256         4,096
n * log2(n)               64       2,048        49,152
n squared                256      65,536    16,777,216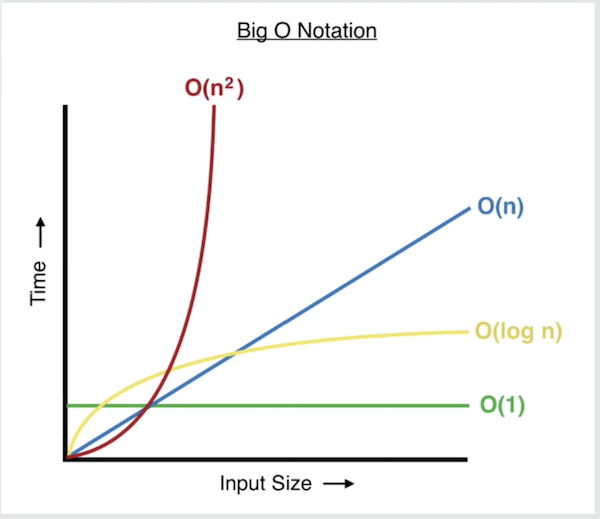
Read growth-rate graphs as scaling illustrations, not timing predictions. For the representative functions, doubling n doubles n and quadruples n², while log2(n) increases by just one.
Why Efficiency Requires More Than Big O
Algorithms with the same growth rate can have different constant costs. Input order, allocation, caching, and expensive comparisons can also affect measured performance. Use complexity to spot scaling problems, then benchmark representative inputs; our JavaScript performance tips cover implementation-level considerations.
Keep time, memory, and behavior separate. A copying operation may protect shared data from accidental changes while requiring more memory. That tradeoff also connects to the emphasis on avoiding unintended changes in functional programming.
Common Algorithms
Sorting Algorithms
Bubble Sort: A Teaching Example
Sorting puts elements in a chosen order. Bubble sort repeatedly compares neighboring elements and swaps them if they're out of order. After each complete left-to-right pass, the largest remaining element is in its final position.
function bubbleSort(numbers) {
  for (let end = numbers.length - 1; end > 0; end--) {
    for (let i = 0; i < end; i++) {
      if (numbers[i] > numbers[i + 1]) {
        const temporary = numbers[i];
        numbers[i] = numbers[i + 1];
        numbers[i + 1] = temporary;
      }
    }
  }
  return numbers;
}

const values = [3, 1, 2];
console.log(bubbleSort(values)); // [1, 2, 3]
console.log(values); // [1, 2, 3]: the input changed
console.log(bubbleSort([])); // []
This implementation mutates the input and returns the same array reference. It handles duplicates and empty arrays. For n elements, it makes n(n − 1)/2 adjacent comparisons, giving O(n²) average- and worst-case time and O(1) auxiliary space.
Because this version has no early-exit check, even already sorted input takes O(n²) time. A version that stops after a pass with no swaps can achieve O(n) best-case time. Bubble sort is useful for learning, not a sensible default for general-purpose sorting.
Other sorting algorithms include merge sort, quicksort, and heapsort. Their performance, memory requirements, and stability differ; stability means preserving the original relative order of elements with equal sorting keys.
JavaScript's Built-In Numeric Sorting
Prefer the built-in method for ordinary application sorting, but know its contract. Array.prototype.sort() sorts in place and returns the same array. Without a comparator, it compares string representations rather than sorting numbers numerically.
const numbers = [1, 10, 2];

console.log(numbers.sort()); // [1, 10, 2]
console.log(numbers.sort((a, b) => a - b)); // [1, 2, 10]
For the finite numbers used here, (a, b) => a - b supplies numeric ascending order. A comparator returns a negative number, zero, or a positive number to indicate ordering—not just a boolean.
When you need to keep the original array unchanged, Array.prototype.toSorted() returns a sorted copy:
const original = [3, 1, 2];
const sorted = original.toSorted((a, b) => a - b);

console.log(sorted); // [1, 2, 3]
console.log(original); // [3, 1, 2]Searching Algorithms
Linear Search
Linear search checks elements one at a time until it finds the target or reaches the end. Unlike maximum-finding, this operation answers “where is this value?”
function linearSearch(numbers, target) {
  for (let i = 0; i < numbers.length; i++) {
    if (numbers[i] === target) return i;
  }
  return -1;
}

console.log(linearSearch([1, 3, 2, 3], 3)); // 1
console.log(linearSearch([1, 3, 2, 3], 9)); // -1
console.log(linearSearch([], 3)); // -1
The result is the first matching zero-based index, or -1 when no match exists. The function doesn't mutate its input. Its best case is O(1), when the first element matches; its worst case is O(n), when the target is absent or last. Auxiliary space is O(1).
Binary Search
Binary search checks the middle of a sorted range. If the target is smaller, it discards the upper half; if larger, it discards the lower half. Sorted order is what makes those eliminations valid.
function binarySearch(numbers, target) {
  let low = 0;
  let high = numbers.length - 1;

  while (low <= high) {
    const mid = low + Math.floor((high - low) / 2);

    if (numbers[mid] === target) return mid;
    if (numbers[mid] < target) {
      low = mid + 1;
    } else {
      high = mid - 1;
    }
  }
  return -1;
}

const sortedArray = [2, 4, 6, 8, 10, 12, 14];
console.log(binarySearch(sortedArray, 10)); // 4
console.log(binarySearch(sortedArray, 9)); // -1
console.log(binarySearch([], 10)); // -1
This function requires ascending numeric order and doesn't check that prerequisite. It returns a matching index or -1, leaves the input unchanged, and may return any matching index when duplicates exist. Its best-case time is O(1), worst-case time is O(log n), and auxiliary space is O(1).
The trace for target 10 visits indices 3, 5, and 4, then returns 4:
| low | high | mid | Value at mid | Next action |
|---|---|---|---|---|
| 0 | 6 | 3 | 8 | Set low to 4 |
| 4 | 6 | 5 | 12 | Set high to 4 |
| 4 | 4 | 4 | 10 | Return 4 |
Linear Search vs. Binary Search
| Algorithm | Input requirement | Best-case time | Worst-case time | Extra space |
|---|---|---|---|---|
| Linear search | Any order | O(1) | O(n) | O(1) |
| Iterative binary search | Sorted in the searched order | O(1) | O(log n) | O(1) |
For one lookup in unsorted data, a linear scan avoids preparation. Sorting with an O(n log n) algorithm just to perform one O(log n) search costs O(n log n) overall, compared with O(n) for the scan.
Repeated searches can justify sorting once. For q searches on unchanged data, that approach has an O(n log n + q log n) upper bound, versus O(qn) for repeated full scans. Whether it pays off depends on the workload and constants; database indexing applies a related preparation-versus-lookup tradeoff, explored in our introduction to MongoDB indexing.
Real World Applications
The same ideas appear in larger systems, usually as components rather than one all-purpose algorithm:
- Social media: Represent people and friendships as a graph—a collection of items and connections. Breadth-first search explores connections layer by layer to find the shortest friendship chain. Friends-of-friends exploration can also generate connection candidates; it isn't a complete feed-ranking system.
- Finance: A moving average repeatedly computes the mean of a window of recent observations, such as prices. Reporting software can use it to smooth a series; NIST's moving-average explanation also shows why this simple approach struggles with significant trends.
- Forecasting: Numerical weather prediction uses mathematical equations and computer calculations to model how the atmosphere changes over time. Here, the inputs and computational demands are much larger than in our array examples.
- E-commerce: Numeric sorting implements lowest-price-first listings. Market-basket analysis finds products purchased together, providing a basis for product suggestions. A separate pricing algorithm might apply explicit stock-based rules; recommendations, ranking, and pricing are different problems.
Common Mistakes
- Solving a bigger problem than necessary: Don't sort a whole list when you only need its maximum.
- Ignoring prerequisites: Binary search isn't correct on arbitrary unsorted input.
- Confusing values and positions: Document whether your function returns a value, an index, or a not-found result.
- Forgetting behavioral requirements: Check mutation, duplicate handling, stability, and empty-input behavior.
- Treating Big O as a stopwatch: Compare growth rates, then measure realistic sizes, input distributions, and memory use.
Start with the simplest correct solution, explain why it works, and count how its work grows. Improve it when your requirements or measurements justify the added complexity.
FAQ
What is an algorithm, and how is it different from a program?
An algorithm is a defined sequence of steps for solving a problem. A program is executable code that implements one or more algorithms, together with details such as input handling and error handling.
Why is Big O notation important?
Big O helps you compare upper bounds on how time or memory requirements grow as input size increases. It doesn't predict exact runtime, include constant factors, or necessarily provide the tightest possible bound.
When should I use binary search instead of linear search?
Use binary search when your array is already sorted in the required order, or when repeated lookups justify preparing it. For one lookup in unsorted data, linear search avoids the cost of sorting first.
Can I always use JavaScript's built-in sorting methods?
Built-in sorting is the right starting point for ordinary arrays, but specialized requirements may need another approach. Array.prototype.sort() mutates its input and compares string representations by default; use a numeric comparator for numbers, or toSorted() when you need a sorted copy.
Does divide and conquer always make an algorithm faster?
No. Divide and conquer splits a problem into smaller subproblems, solves them, and combines their results, as merge sort does. Its cost depends on the number and size of subproblems and the splitting and combining work; splitting alone guarantees no speedup.
Further Reading
- NIST: Algorithm — a concise definition and related algorithm categories.
- NIST: Big O notation — the meaning of asymptotic upper bounds.
- Princeton: Algorithms and Data Structures Cheatsheet — growth rates, sorting properties, and tradeoffs.
- Princeton: Sorting and Searching — binary search, merge sort, and exercises.
- NIST: Bubble Sort — adjacent swaps and the early-exit improvement.
- MDN: Array.prototype.sort() — comparators, mutation, and stability.
- MDN: Array.prototype.toSorted() — sorting without changing the original array.
- Princeton: Undirected Graphs — breadth-first search and social-network paths.
